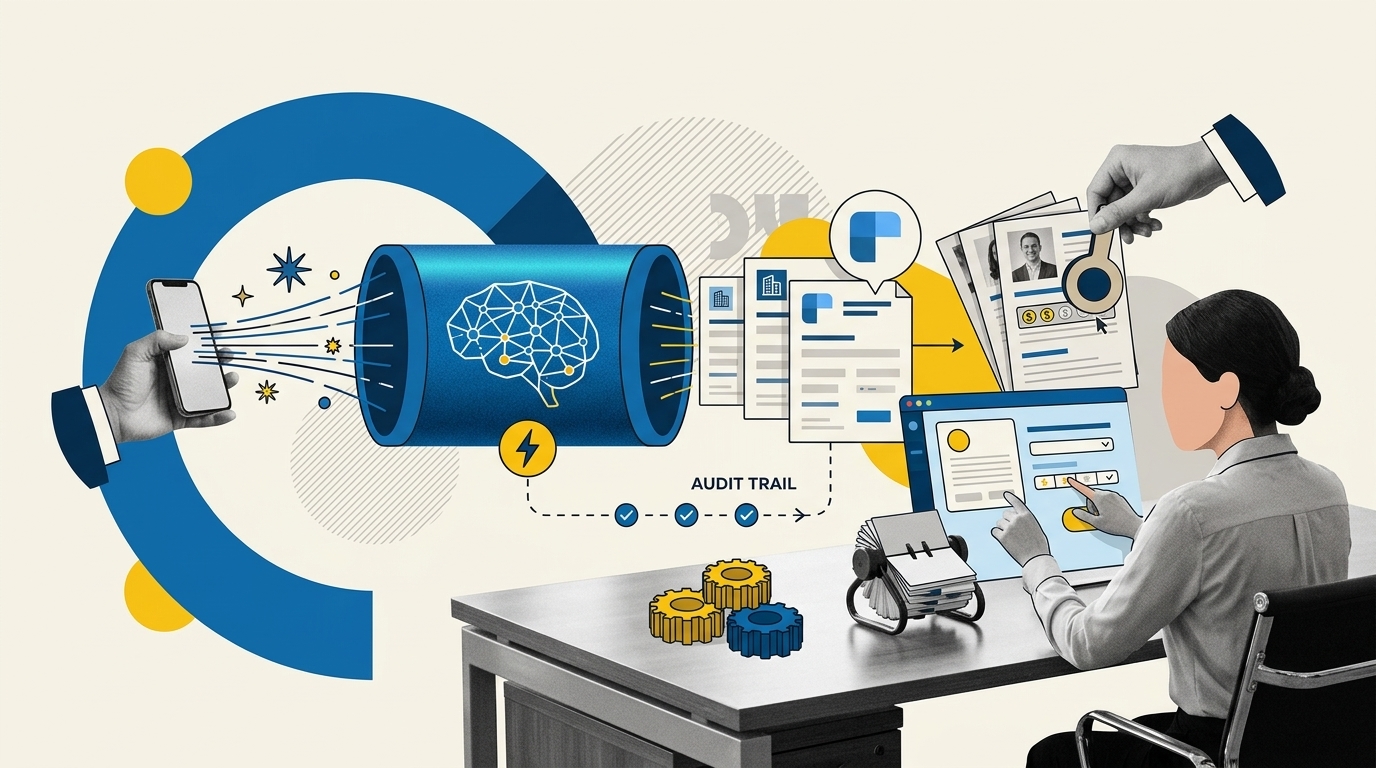
Implementing automated lead scoring with AI in B2B environments delivers the highest operational value when constructed as a two-stage hybrid pipeline: deterministic rule filtering handles objective firmographic criteria, while constrained large language models (LLMs) evaluate unstructured text responses such as self-reported challenges and intended use cases. This research-based guide demonstrates how growth and marketing operations teams can connect webhooks, enrichment APIs, OpenAI structured outputs, and CRM architectures to build an auditable, transparent qualification pipeline without deploying complex enterprise software suites.
Key Takeaways
- Separate rules from probabilistic models: Use deterministic logic for verifiable firmographics (company size, location, domain validity) and reserve AI exclusively for semantic classification of qualitative form responses.
- Enforce strict JSON schemas: Using OpenAI Structured Outputs with strict schema constraints guarantees reliable CRM payload ingestion and eliminates formatting failures or hallucinated categories.
- Preserve a complete CRM audit trail: Write confidence scores, underlying reasoning, model version tags, and timestamp metadata directly to dedicated CRM property groups so sales teams understand why each score was assigned.
- Maintain human override controls: Comply with data protection regulations (such as GDPR Article 21 and Article 22) by establishing human review states, manual overrides, and clear objection channels for prospective buyers.
- Account for API failure states: Enriching payloads asynchronously and implementing fallback queues prevents broken lead routing whenever third-party data providers fail to match a domain.
The Hybrid Qualification Model: Rules vs. Probabilistic Classification
Many early marketing attempts at AI lead scoring fail because teams ask a language model to perform holistic commercial judgments from raw contact submissions. Handing an unconstrained prompt an email address, a job title, and a company name, then asking “Is this lead an Ideal Customer Profile (ICP) fit?”, yields unpredictable results. Large language models are probabilistic text prediction engines. They do not possess real-time corporate registry access, cannot independently verify employee counts, and will produce inconsistent scores across identical lead profiles depending on subtle variations in wording.
Before configuring automated scoring logic, growth teams must establish their Ideal Customer Profile boundaries using grounded customer data. Applying the methodology outlined in our AI customer research workflow allows operators to extract recurring buyer pain points, company profile markers, and disqualification indicators directly from validated sales calls and interview transcripts. Grounding criteria in research ensures qualification parameters reflect real operational dynamics rather than speculative assumptions.
A reliable architecture decouples qualification into two explicit, sequential layers:
- Deterministic Screening (Rules Engine): Hard gates that evaluate concrete, binary attributes. If a company operates in an unsupported geography, uses a free consumer webmail provider (such as @gmail.com or @yahoo.com), or falls below a mandatory employee threshold, the record is immediately categorized without spending computational resources on AI analysis.
- Probabilistic Classification (LLM Engine): Applied strictly to qualitative fields where deterministic filters fail. This includes open-ended form inputs such as “What operational bottleneck are you trying to resolve?” or “Describe your intended deployment timeline.” The model evaluates nuance, context, and semantic alignment against a documented ideal customer profile rubric.
By enforcing this division, the system remains transparent, inspectable, and resilient against model drift.
Step 1: Inbound Webhook Ingestion and Sanitization
The pipeline begins when a prospective buyer submits an inbound demonstration or contact form. Rather than relying on rigid native CRM forms, modern stacks transmit form payloads via HTTP POST requests to an automation platform such as Make or Zapier.
According to the Zapier webhook documentation, incoming webhook triggers parse standard JSON request bodies up to 2MB into discrete step variables, allowing downstream filters to branch dynamically based on specific key-value pairs.
To prepare inbound payloads for deterministic screening and LLM evaluation, the ingestion step must execute three basic sanitation procedures:
- Email Domain Extraction: Isolate the domain string following the “@” symbol (for example,
[email protected]yieldsenterprise.com) while stripping trailing spaces and converting characters to lowercase. - Consumer Domain Filtering: Check the extracted domain against a curated list of generic email providers. Inbound records with consumer addresses are routed to automated nurture tracks or assigned a lower priority tier before external API credits are consumed.
- Payload String Normalization: Clean qualitative text inputs by removing leading and trailing whitespace, stripping excessive control characters or emojis, and truncating strings beyond reasonable operational limits (such as 1,500 characters) to prevent token bloat during subsequent inference calls.
Step 2: Firmographic Enrichment and Deterministic Filtering
Once a valid corporate domain is isolated, the workflow queries a B2B firmographic data provider. Rather than burdening prospects with lengthy 10-field web forms, the automation enriches the record in the background using the corporate domain as the unique identifier.
As documented in the Clearbit enrichment payload structure, standardized enrichment APIs return structured company profiles containing categorical data such as employee headcount bands (employeesRange), estimated revenue figures, industry categorizations, and tagged software technologies. This provides the exact quantitative data required for rule-based gating.
Deterministic Gating Rules Matrix
The automation applies zero-tolerance operational rules to the enriched payload before engaging any generative AI models:
| Data Attribute | Criterion | Pipeline Action |
|---|---|---|
| Email Domain Type | Consumer address (e.g., gmail, outlook) | Assign Tier D; bypass enrichment; route to self-serve nurture. |
| Geographic Headquarters | Country outside service coverage | Mark Disqualified: Out of Territory; bypass LLM processing. |
| Employee Headcount | Below product minimum (e.g., < 10 employees) | Assign Tier C (Sub-scale); route to community or self-guided trial. |
| Existing Customer Match | Domain matches active client account in CRM | Route directly to Customer Success; skip acquisition pipeline. |
| Corporate Domain Status | Matches ICP threshold (> 25 employees, target industry) | Pass payload to Stage 2 (LLM qualitative classification). |
Step 3: Constrained LLM Classification of Qualitative Responses
When an inbound lead clears the deterministic gates, the qualitative form submission is evaluated. Traditional scoring tools assign arbitrary point values to specific keywords (such as +10 points for “enterprise” or +5 points for “migration”). This approach frequently misinterprets negative context, such as “we do not need enterprise migration.”
Using a large language model allows the system to interpret intent, technical readiness, and operational urgency accurately. However, marketing systems require deterministic formatting from probabilistic engines to prevent broken pipeline executions.
According to the OpenAI Structured Outputs guide, configuring API requests with response_format: { type: "json_schema" } and setting strict: true forces the underlying model to conform entirely to a defined JSON Schema through constrained decoding. This mathematical guarantee prevents missing keys, unexpected markdown wrappings, and unauthorized category values.
System Prompt Construction
The system prompt must act as a strict evaluator rather than a conversational agent. Provide the model with explicit definitions for each classification tier, instructions to evaluate urgency and technical alignment, and strict limits forbidding speculation beyond the text provided by the lead:
{
  "role": "system",
  "content": "You are a B2B Marketing Operations Qualification Engine. Your sole function is to evaluate qualitative inbound form responses against our strict Ideal Customer Profile rubric. Classify the user response into one of three tiers: HIGH_FIT, MEDIUM_FIT, or LOW_FIT. Provide an objective confidence score between 0.00 and 1.00, select the primary operational driver, and summarize your evaluation in two concise sentences. Never assume facts not stated in the input text. If the submission lacks meaningful business context, assign LOW_FIT with low confidence."
}
Handling the Confidence Threshold
The model must return a numerical confidence score representing its certainty regarding the semantic match. Growth teams should configure an automated decision boundary:
- High Confidence (≥ 0.75): The pipeline accepts the model’s tier classification and proceeds immediately to automated routing (e.g., assigning HIGH_FIT leads directly to an account executive’s calendar queue).
- Low Confidence (< 0.75): The record is flagged as
NEEDS_HUMAN_REVIEW. Instead of being automatically accepted or disqualified, the submission routes to an inbound sales development representative (SDR) triage queue for manual qualification.
Step 4: CRM Writeback and Audit Property Architecture
Scoring workflows must never alter CRM records invisibly. When sales representatives cannot understand why a contact was marked as high or low priority, they lose trust in marketing automation. Every automated decision must leave a traceable audit trail directly inside the contact record.
According to the HubSpot CRM Properties API documentation, CRM systems support custom property definitions and property groups across text, numerical, boolean, and enumeration types. Creating a dedicated property group ensures operational data remains distinct from manual sales notes.
Recommended CRM Custom Property Schema
| Internal Property Name | Field Type | Purpose and Description |
|---|---|---|
ai_qualification_tier |
Enumeration (Dropdown) | Values: HIGH_FIT, MEDIUM_FIT, LOW_FIT, PENDING_REVIEW, DISQUALIFIED. |
ai_qualification_confidence |
Number (Decimal) | The model’s self-assessed certainty metric (0.00 to 1.00). |
ai_qualification_reasoning |
Multi-line Text | The 2-sentence rationale returned by the structured output schema. |
ai_model_version |
Single-line Text | Identifies the exact provider model (e.g., gpt-4o-mini-2024-07-18). |
ai_qualification_timestamp |
Datetime | Precise UTC timestamp when the scoring webhook executed. |
ai_human_override_status |
Enumeration (Dropdown) | Values: NONE, CONFIRMED_AI, OVERRIDDEN_QUALIFIED, OVERRIDDEN_DISQUALIFIED. |
ai_human_override_reason |
Multi-line Text | Mandatory text note entered by sales reps when overturning an AI decision. |
Governance, Data Privacy, and Human Override Controls
Automated profiling and scoring workflows must adhere to international privacy frameworks. Marketing operations teams cannot treat inbound personal data as an unregulated sandbox.
Under the UK General Data Protection Regulation and EU GDPR, automated lead scoring constitutes profiling. According to the UK ICO guidance on automated decision-making and profiling, individuals possess an absolute legal right under Article 21 to object to profiling conducted for direct marketing purposes. Furthermore, where solely automated decisions carry significant or legal consequences (Article 22), data controllers must implement meaningful human intervention, providing individuals the ability to contest the decision and obtain human review.
To ensure strict regulatory and operational compliance:
- Exclude Protected Attributes: Never pass or permit the language model to score leads using demographic markers, personal characteristics, or sensitive categories. Evaluation criteria must focus exclusively on stated commercial requirements and organizational firmographics.
- Enforce Meaningful Human Review: Set up automated CRM triggers that freeze automated disqualifications whenever a prospect requests direct review, or whenever a sales representative questions a scoring outcome.
- Design One-Click Sales Overrides: Provide sales representatives with an explicit override mechanism in the CRM sidebar. When a representative changes
ai_human_override_statusfromNONEto an override state, automated routing stops adjusting that record, preserving salesperson autonomy. - Maintain Model Traceability: Because prompts and models evolve, logging the model version and prompt iteration in the contact record ensures operators can trace and audit historical scoring decisions across previous quarters.
API Error Handling, Rate Limits, and Operating Costs
Production workflows must account for real-world API friction, including third-party latency, match failures, and execution limits across no-code tools and model endpoints.
Error Handling Architecture
When an enrichment provider returns a 404 (Domain Not Found) or experiences an outage, the automation must not crash or drop the inbound lead. Construct fallback pathways:
- Enrichment Fallback: If the enrichment step fails, route the lead immediately to a secondary tier (
ENRICHMENT_FAILED) and write the raw form inputs to the CRM. The contact remains visible to sales reps rather than disappearing in an execution queue. - LLM Timeout Handling: Wrap inference calls with a 15-second timeout and a single automatic retry. If the model API returns a 429 (Rate Limit Exceeded) or 500 error, write the record as
PENDING_AI_EVALUATIONand enqueue it for batch reprocessing. - Webhook Execution Limits: Monitor payload ingestion limits on automation platforms (such as Zapier’s 2MB payload ceiling). While standard form text rarely approaches this limit, automated workflows processing multi-page form responses or attached files must parse text streams selectively.
Unit Cost Analysis
Operating a custom two-stage pipeline is considerably more economical for lean teams than enterprise qualification software suites requiring five-figure annual contracts. The variable operational costs break down into three manageable layers:
- Automation Platform Costs: In platforms like Make or Zapier, a four-step pipeline (Webhook → Enrichment → OpenAI → CRM Writeback) consumes approximately 4 tasks per inbound submission. On mid-tier plans, this represents less than $0.02 per lead processed.
- Firmographic Enrichment: Third-party lookup APIs typically cost between $0.05 and $0.20 per successful domain resolution, depending on contract volume.
- LLM Inference Costs: Utilizing lightweight structured models (such as
gpt-4o-mini) processing an average of 400 input tokens and 150 output tokens costs less than $0.001 per submission.
Total direct operational expenditure typically ranges between $0.07 and $0.22 per inbound lead, offering small and mid-market growth teams an auditable scoring engine at a fraction of enterprise software overhead.
Reusable Assets: Scoring Rubric, JSON Schema, and QA Checklist
The following assets provide a ready-to-implement template for configuring qualification logic, constraining model outputs, and auditing production runs.
1. Two-Stage B2B Scoring Rubric
| Lead Dimension | Evaluation Method | Qualified State (High Fit) | Disqualified State (Low Fit) |
|---|---|---|---|
| Corporate Domain | Deterministic Filter | Custom business domain; valid MX records. | Free consumer domain (gmail, yahoo, hotmail). |
| Company Headcount | Deterministic Filter | ≥ 25 employees (via enrichment API). | < 10 employees (sub-scale). |
| Target Industry | Deterministic Filter | Matches core vertical taxonomy. | Excluded sector (e.g., retail consumer goods). |
| Stated Problem Fit | LLM Classification | Expresses direct bottleneck matching product core. | Vague inquiry or irrelevant operational scope. |
| Deployment Urgency | LLM Classification | Explicit immediate timeline (< 3 months). | Academic curiosity, student research, or general browse. |
2. Strict JSON Schema for OpenAI Structured Outputs
Use the following schema definition inside your API payload configuration to enforce constrained decoding:
{
  "type": "object",
  "properties": {
    "qualification_tier": {
      "type": "string",
      "enum": ["HIGH_FIT", "MEDIUM_FIT", "LOW_FIT"],
      "description": "The qualification tier based strictly on ICP problem alignment."
    },
    "confidence_score": {
      "type": "number",
      "minimum": 0,
      "maximum": 1,
      "description": "Confidence in the assessment based on textual evidence provided."
    },
    "primary_driver": {
      "type": "string",
      "enum": [
        "CORE_WORKFLOW_BOTTLENECK",
        "SCALE_AND_EFFICIENCY",
        "EXPLORATORY_EVALUATION",
        "FEATURE_MISMATCH",
        "INSUFFICIENT_CONTEXT"
      ],
      "description": "The primary operational reason explaining the tier decision."
    },
    "evaluation_rationale": {
      "type": "string",
      "description": "A concise two-sentence objective rationale explaining the classification."
    }
  },
  "required": [
    "qualification_tier",
    "confidence_score",
    "primary_driver",
    "evaluation_rationale"
  ],
  "additionalProperties": false
}
3. Production Deployment QA Checklist
| Validation Stage | Verification Checkpoint | Pass Criteria |
|---|---|---|
| Webhook Security | Payload secret validation | Webhook rejects unauthorized POST calls missing authentication headers. |
| Domain Parsing | Edge-case email formatting | Accurately isolates domains from sub-addresses (e.g., [email protected]). |
| Enrichment Failover | Unmatched domain handling | Workflow routes un-enriched leads to SDR fallback queue without terminating. |
| Schema Adherence | OpenAI strict schema test | API requests pass validation with additionalProperties: false on all objects. |
| CRM Property Types | HubSpot / CRM type matching | Confidence decimals and tier enum strings map to identical CRM field types. |
| Human Override | Manual state persistence | Updating ai_human_override_status locks record against automated re-scoring. |
| Privacy Audit | Direct marketing opt-out check | Opt-out requests automatically clear contact from scoring workflows. |
Frequently Asked Questions
Can language models replace traditional rule-based lead scoring entirely?
No. Relying entirely on language models for lead scoring introduces unnecessary cost, operational fragility, and hallucination risks. Objective firmographic factors like employee count, headquarters location, and domain legitimacy are handled far more reliably and affordably by deterministic rules and enrichment APIs. Language models should only be deployed where rules fail: classifying unstructured qualitative text responses.
How do we handle leads that provide personal email addresses like Gmail?
Leads submitting personal email addresses should bypass paid enrichment and LLM classification entirely. Configure an immediate deterministic filter at Step 1 that assigns these contacts to a low-touch educational nurture track or prompts them with an automated follow-up asking for a corporate email address to unlock enterprise features.
What should sales representatives do when they disagree with an AI qualification score?
Sales representatives should use the CRM human override fields (such as ai_human_override_status and ai_human_override_reason) in the contact record. Setting an override must immediately halt automated updates on that record. Marketing operations teams should review overrides weekly to detect whether prompt rubrics or confidence thresholds need recalibration.
Does automated lead scoring require explicit consent under GDPR?
Under GDPR and UK GDPR, automated scoring used for direct marketing constitutes profiling and typically relies on legitimate interests or consent. However, Article 21 grants prospects an absolute right to object to profiling for direct marketing at any time. If an individual objects, processing for marketing profiling must cease immediately. Organizations must communicate this right clearly and maintain technical controls to remove opted-out contacts from scoring pipelines.
